Shiyi Lan 兰石懿

I am a Staff Research Scientist at Waymo, working on Waymo Gemini. My goal is to build foundation models and agents that perceive, reason, plan, and act across digital and physical environments.

My research focuses on model architectures and data curation for capability development through pretraining, target-domain mid-training, reward modeling, and reinforcement learning. I study accuracy-efficiency co-design, jointly optimizing architectures and kernels for task accuracy and end-to-end inference latency on target devices.

I received my Ph.D. in Computer Science from the University of Maryland, College Park in 2022, advised by Prof. Larry S. Davis, and my B.S. from Fudan University in 2018.

Email: voidrank [at] gmail [dot] com

CV   /   Google Scholar   /   GitHub

Portrait of Shiyi Lan
Experience

Waymo, Staff Research Scientist 2026–Present
Pretraining, target-domain mid-training, and RL post-training for Waymo Gemini. Developing diffusion-model post-training methods and RL training infrastructure, with autonomous driving as the primary application.

  • Reward modeling. Led critic-based reward design under teacher-student information asymmetry. Grounded rewards in student-observable evidence to avoid reinforcing unsupported reasoning even when final outcomes were correct. Developed format and process rewards.
  • Accuracy-efficiency co-design. Co-optimized pretraining architectures and kernels for task accuracy and end-to-end inference latency on target devices, developing and evaluating Gated DeltaNet and MuxNet variants, state experts, and multi-exit designs. Guided architectural decisions through empirical evaluation of model quality, training stability, and on-device efficiency.

NVIDIA Research, Senior Research Scientist 2023–2026
Core member of Nemotron-Diffusion-VL, responsible for data recipes, evaluation, VLM implementation, and training infrastructure. Led research on multimodal perception-to-action agents, including language-grounded scene understanding, trajectory generation, teacher-student distillation, closed-loop evaluation, and reinforcement learning, applied to end-to-end autonomous driving through the HydraMDP family and OmniDrive.

NVIDIA Research, Research Scientist 2022–2023
Core team member of NV-CLIP; led pre-training and resolved loss-divergence issues. Developed MMAL, the CVPR 2023 mask auto-labeling framework.

NVIDIA Research, Research Intern 2020
Researched weakly supervised instance segmentation on MS COCO.

ByteDance AI Lab, Research Intern 2018
Contributed to a recommendation-system warmup project that reduced daily warmup cost by five million CNY.

Signature Projects
  • Nemotron-Diffusion-VL — Core member of NVIDIA's first diffusion VLM.
  • End-to-End Driving at Scale — 1st place at CVPR 2025 and CVPR 2024 (Team Lead).
  • 3D Occupancy Challenge — 1st place at CVPR 2023.
  • Robust Vision Challenge — 1st place in the 2022 semantic segmentation track.
  • MS COCO 2017 — 1st place in object detection and 2nd place in instance segmentation.
Recent & Selected Publications

For a complete list, please see my Google Scholar profile.

HAD autonomous driving paper
HAD: Combining Hierarchical Diffusion with Metric-Decoupled RL for End-to-End Driving
Wenhao Yao, Xinglong Sun, Zhenxin Li, Shiyi Lan, Zi Wang, Jose M. Alvarez, Zuxuan Wu
Under submission, 2026
paper
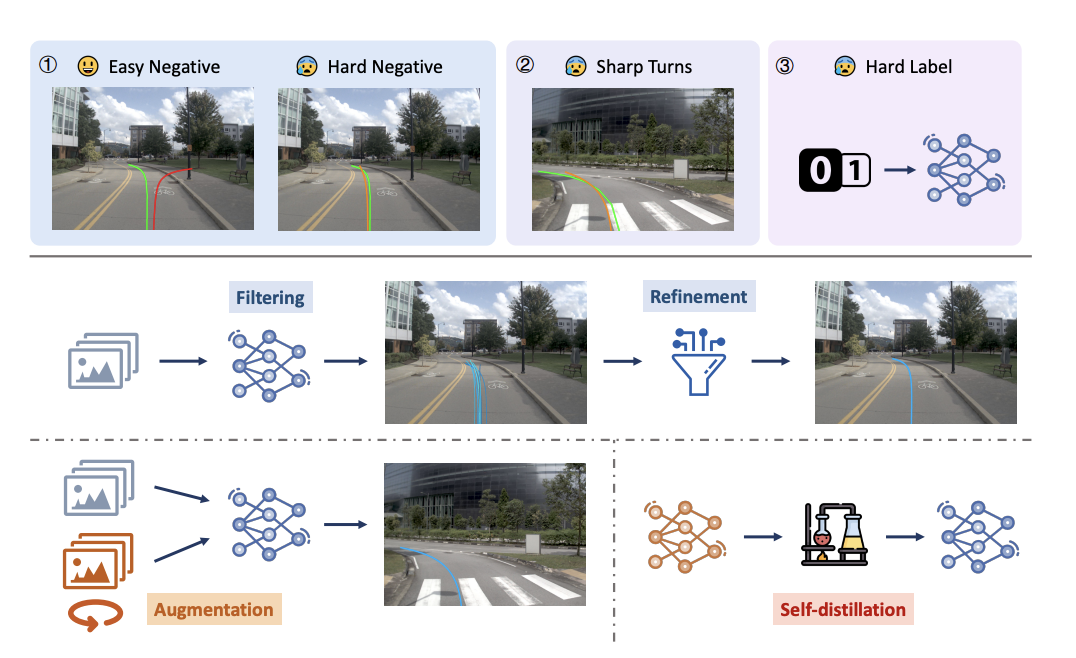
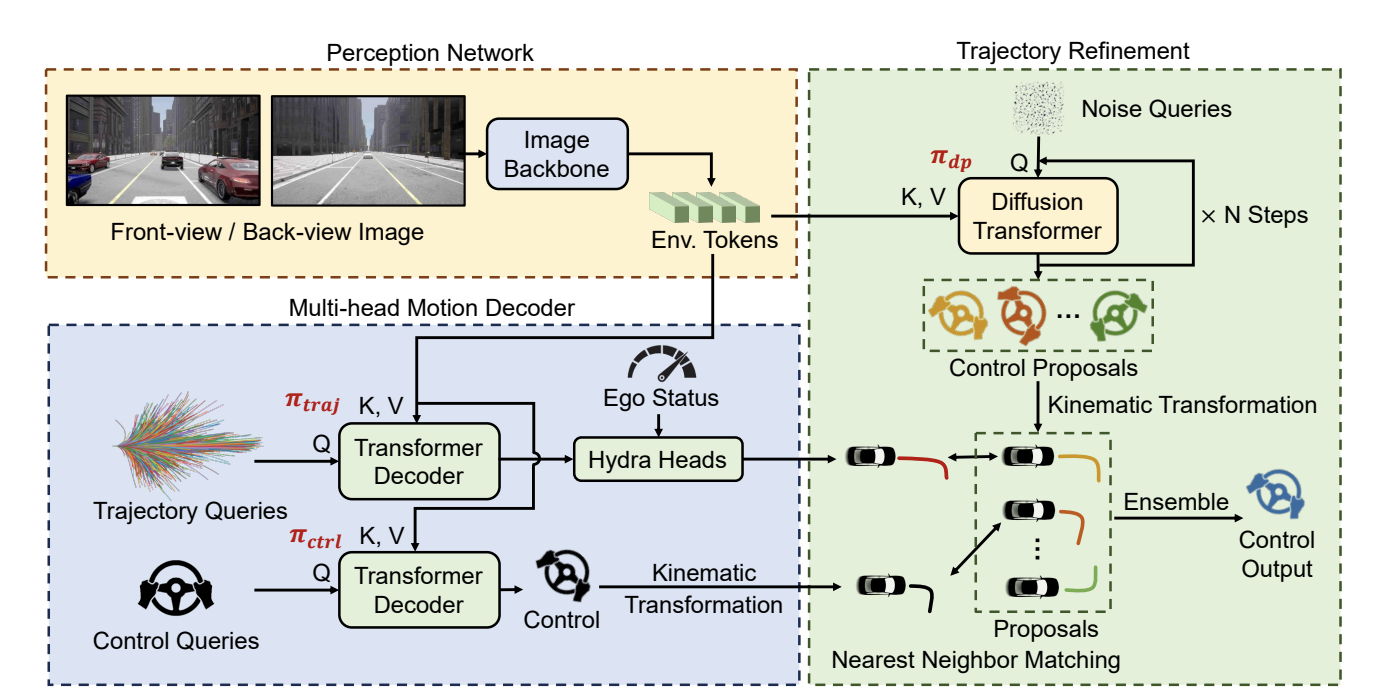
DriveSuprim figure
DriveSuprim: Towards Precise Trajectory Selection for End-to-End Planning
W Yao, Z Li, Shiyi Lan, Z Wang, X Sun, JM Alvarez, Z Wu
AAAI, 2026
paper / arXiv
Hydra-MDP paper
Hydra-MDP: End-to-End Multimodal Planning with Multi-Target Hydra-Distillation
Zhenxin Li, Kailin Li, Shihao Wang, Shiyi Lan, Zhiding Yu, Yishen Ji, Zhiqi Li, Ziyue Zhu, Jan Kautz, Zuxuan Wu, Yu-Gang Jiang, Jose M. Alvarez
arXiv, 2024
paper / code
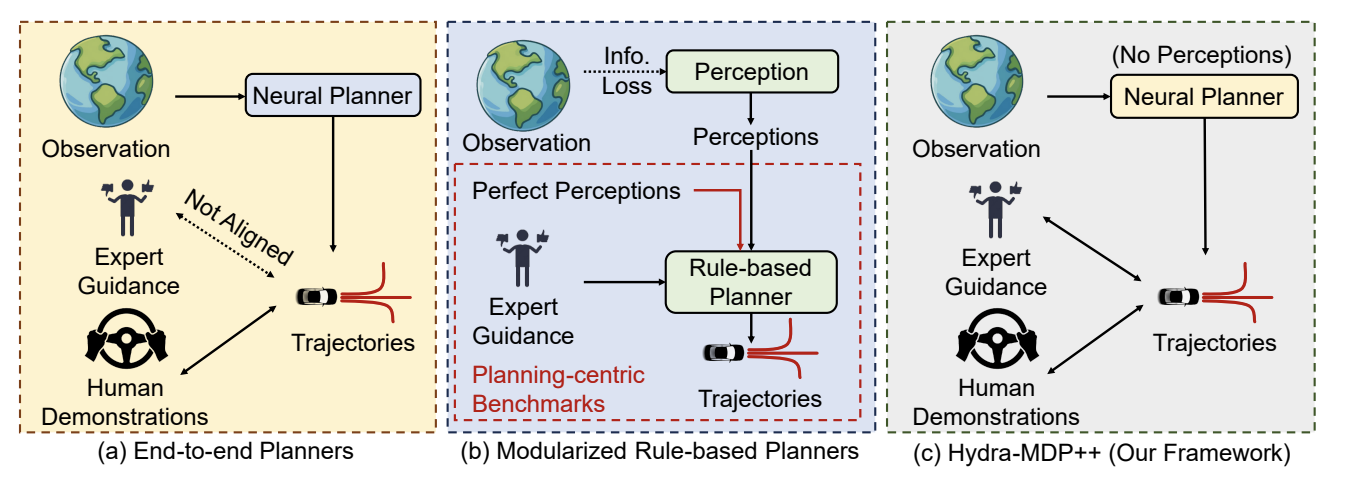
Hydra-MDP++ figure
Hydra-MDP++: Advancing End-to-End Driving via Expert-Guided Hydra-Distillation
K Li, Z Li, Shiyi Lan, Y Xie, Z Zhang, J Liu, Z Wu, Z Yu, JM Alvarez
arXiv, 2025
paper / code
Hydra-NeXt figure
Hydra-NeXt: Robust Closed-Loop Driving with Open-Loop Training
Z Li, S Wang, Shiyi Lan, Z Yu, Z Wu, JM Alvarez
ICCV, 2025
paper / code
Centaur figure
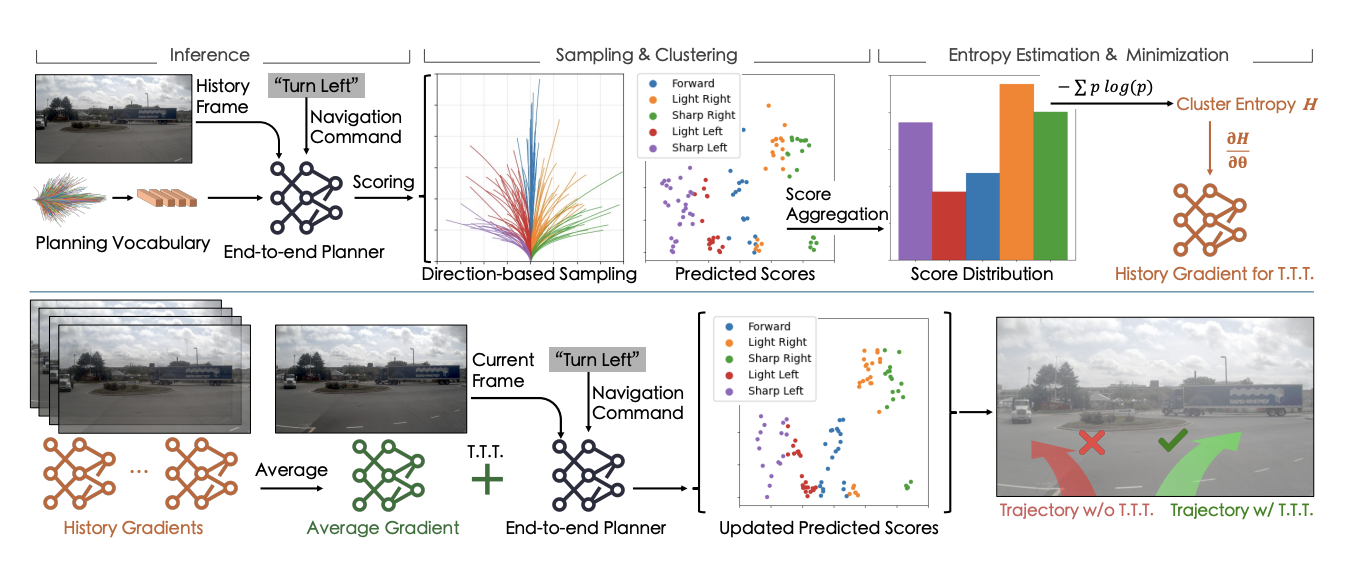
Centaur: Robust End-to-End Autonomous Driving with Test-Time Training
C Sima, K Chitta, Z Yu, Shiyi Lan, P Luo, A Geiger, H Li, JM Alvarez
arXiv, 2025
paper
Autonomous driving collision scenarios paper
Enhancing Autonomous Driving Safety with Collision Scenario Integration
Z Wang, Shiyi Lan, X Sun, N Chang, Z Li, Z Yu, JM Alvarez
arXiv, 2025
paper
Eagle 2 vision-language model paper
Eagle 2: Building Post-Training Data Strategies from Scratch for Frontier Vision-Language Models
Z Li, G Chen, S Liu, S Wang, V VS, Y Ji, Shiyi Lan, H Zhang, Y Zhao
arXiv, 2025
paper
Cosmos world foundation model paper
Cosmos World Foundation Model Platform for Physical AI
N Agarwal, A Ali, M Bala, Y Balaji, E Barker, T Cai, P Chattopadhyay, Shiyi Lan, et al.
arXiv, 2025
paper
StreamChat streaming video paper
StreamChat: Chatting with Streaming Video
J Liu, Z Yu, Shiyi Lan, S Wang, R Fang, J Kautz, H Li, JM Alvarez
arXiv, 2024
paper
OmniDrive paper
OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning
S Wang, Z Yu, X Jiang, Shiyi Lan, M Shi, N Chang, J Kautz, Y Li, JM Alvarez
CVPR, 2025
paper
MDP model pruning paper
MDP: Multidimensional Vision Model Pruning with Latency Constraint
X Sun, B Lakshmanan, M Shen, Shiyi Lan, J Chen, JM Alvarez
CVPR, 2025
paper
ProLab semantic segmentation paper
A Semantic Space is Worth 256 Language Descriptions: Make Stronger Segmentation Models with Descriptive Properties
J Xiao, Z Zhou, W Li, Shiyi Lan, J Mei, Z Yu, B Zhao, A Yuille, Y Zhou, C Xie
ECCV, 2024
paper / code
FocalFormer3D paper
FocalFormer3D: Focusing on Hard Instance for 3D Object Detection
Y Chen, Z Yu, Y Chen, Shiyi Lan, A Anandkumar, J Jia, JM Alvarez
ICCV, 2023
paper
FB-OCC occupancy prediction paper
FB-OCC: 3D Occupancy Prediction based on Forward-Backward View Transformation
Z Li, Z Yu, D Austin, M Fang, Shiyi Lan, J Kautz, JM Alvarez
CVPR Workshop on End-to-End Autonomous Driving, 2023
paper / code
Vision Transformers Are Good Mask Auto-Labelers paper
Vision Transformers Are Good Mask Auto-Labelers
Shiyi Lan, X Yang, Z Yu, Z Wu, JM Alvarez, A Anandkumar
CVPR, 2023
paper
Robust Vision Challenge solution paper
1st Place Solution of The Robust Vision Challenge (RVC) 2022 Semantic Segmentation Track
J Xiao, Z Xu, Shiyi Lan, Z Yu, A Yuille, A Anandkumar
arXiv, 2022
paper
DiscoBox paper
DiscoBox: Weakly Supervised Instance Segmentation and Semantic Correspondence from Box Supervision
Shiyi Lan, Zhiding Yu, Christopher Choy, Subhashree Radhakrishnan, Guilin Liu, Yuke Zhu, Larry S. Davis, Anima Anandkumar
ICCV, 2021
arXiv / code

The first-place weakly supervised instance segmentation model using box labels.

M3DETR paper
M3DETR: Multi-representation, Multi-scale, Mutual-relation 3D Object Detection with Transformers
Tianrui Guan*, Jun Wang*, Shiyi Lan†, Rohan Chandra, Zuxuan Wu, Larry S. Davis, Dinesh Manocha
† Correspondence Author. * means equal contribution.
WACV, 2022
arXiv / code

The multi-representation, multi-scale, mutual-relation 3D object detector with transformers.

InfoFocus paper
InfoFocus: 3D Object Detection for Autonomous Driving with Dynamic Information Modeling
Jun Wang*, Shiyi Lan*, Mingfei Gao, Yi Wu, Larry S. Davis,
* means equal contribution.
ECCV, 2020
arXiv

3D Object Detection with the effective dynamic attention module.

AdaViT paper
AdaViT: Adaptive Vision Transformers for Efficient Image Recognition
Lingchen Meng, Hengduo Li, Bor-Chun Chen, Shiyi Lan, Zuxuan Wu, Yu-Gang Jiang, Ser-Nam Lim
CVPR, 2022
paper
SaccadeNet paper
SaccadeNet: A Fast and Accurate Object Detector
Shiyi Lan, Zhou Ren, Yi Wu, Larry S. Davis, Gang Hua
CVPR, 2020
arXiv / code

A real-time and high-performance object detector.

Geo-CNN paper
Modeling Local Geometric Structure of 3D Point Clouds Using Geo-CNN
Shiyi Lan, Ruichi Yu, Gang Yu, Larry S. Davis
CVPR, 2019
arXiv / code

Modeling point cloud by leveraging geometric information of point clouds.

FastMask paper
FastMask: Segment Multi-scale Object Candidates in One Shot
Hexiang Hu*, Shiyi Lan*, Yuning Jiang, Zhimin Cao, Fei Sha
* means equal contribution. CVPR, 2017 (Spotlight)
arXiv / code

Generating instance segmentation candidates by leveraging multi-scale feature pyramids.

Additional Honors
  • ICPC 2015 Shenyang Regional, Silver Medal (Rank 18/≈300)
  • National Olympiad in Informatics of China 2013, Bronze (Rank 122/≈400)
Patents
Academic Services
Conference Reviewer: AAAI'20, CVPR'21, ICCV'21, CVPR'22, ECCV'22; Journal Reviewer: IJCV'20